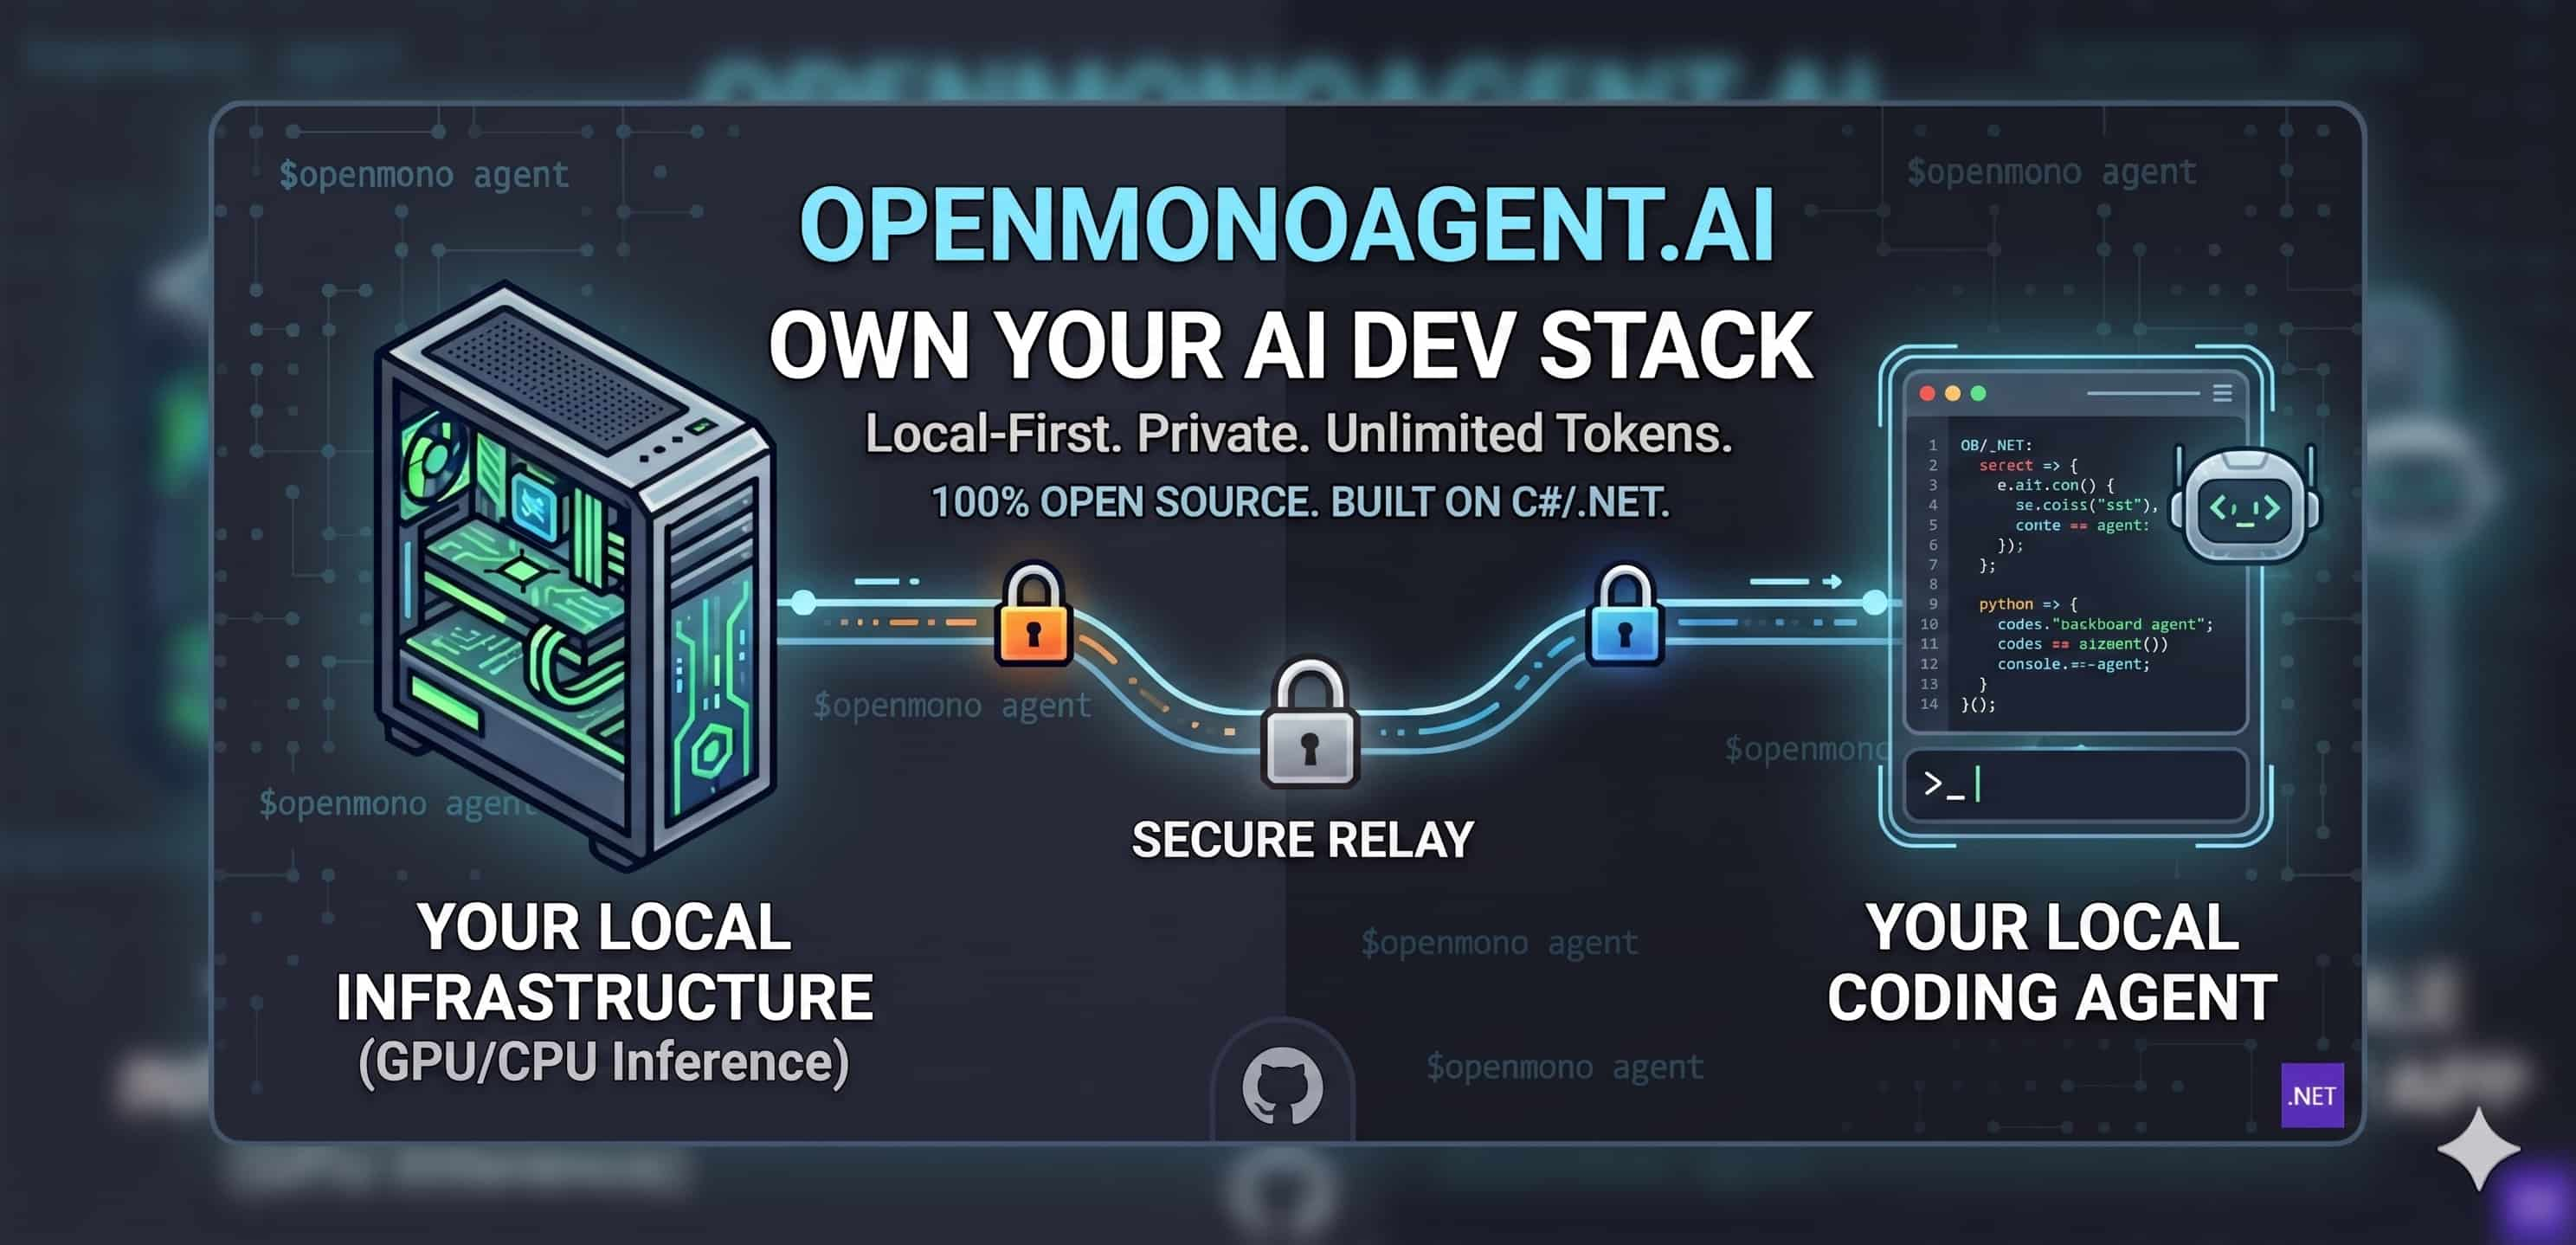
Your machine. Your agent. Use it from anywhere. OpenMonoAgent.ai is a terminal-native coding agent powered by local LLMs: 100% open source, free forever, and installed with a single command. Proudly built on C#/.NET, because AI tooling should be infrastructure, not a subscription.
Want it on your own servers? We install and support private OpenMonoAgent deployments.
"AI shouldn't be a subscription you rent. It should be infrastructure you own - sitting on your desk, serving your code, answering only to you."
- The StartupHakk democratize-AI thesis
We also install and support private OpenMonoAgent deployments on your own hardware.Get in touch.
| Hardware | Memory | Model | tok/s |
|---|---|---|---|
| Ryzen 9 7940HS / 780m DDR5 dual-channel | 32 GB RAM | Ternary-Bonsai 2 27BFULL ACCURACY | ~8 to 10 |
| Apple M5 Pro 307 GB/s bandwidth | 64 GB RAMi | Qwen 3.6 35B A3BFULL ACCURACY | ~45 to 48 |
| RTX 3090 936 GB/s bandwidth | 24 GB VRAM | Qwen 3.8 27BFULL ACCURACY | ~42 to 45 |
| RTX 3090 RECOMMENDED 936 GB/s bandwidth | 24 GB VRAM 64 GB+ system RAM | Qwen 3.8 Flash-NextFULL ACCURACY | ~55 to 60 |
| RTX 4090 1,008 GB/s bandwidth | 24 GB VRAM | Qwen 3.8 27BFULL ACCURACY | ~47 to 50 |
| RTX 5090 1,792 GB/s bandwidth | 32 GB VRAM 64 GB+ system RAM | Qwen 3.8 Flash-NextFULL ACCURACY | ~180 |
| RTX 3060 360 GB/s bandwidth | 12 GB VRAM | Ternary-Bonsai 2 27BFULL ACCURACY | ~20 to 32 |
| RTX 4060 Ti → 4080 288 to 717 GB/s bandwidth | 16 GB VRAM | Qwen 3.8 27BFULL ACCURACY | ~20 to 42 |
llama.cpp is built in. Setup reads your hardware and picks the best model for it. GPU runs Qwen 3.8 27B, or Qwen 3.8 Flash-Next when a 24 GB card has 48 GB+ of system RAM behind it. SoC machines like the Ryzen 9 7940HS run Bonsai 2 27B, where speed tracks RAM bandwidth. Smaller GPUs get the same 27B, quantized to fit their VRAM. No rate limits, no clock watching, no bills.
Not sure what hardware you need?
Tell us your budget and machine. We'll recommend the right model and setup.
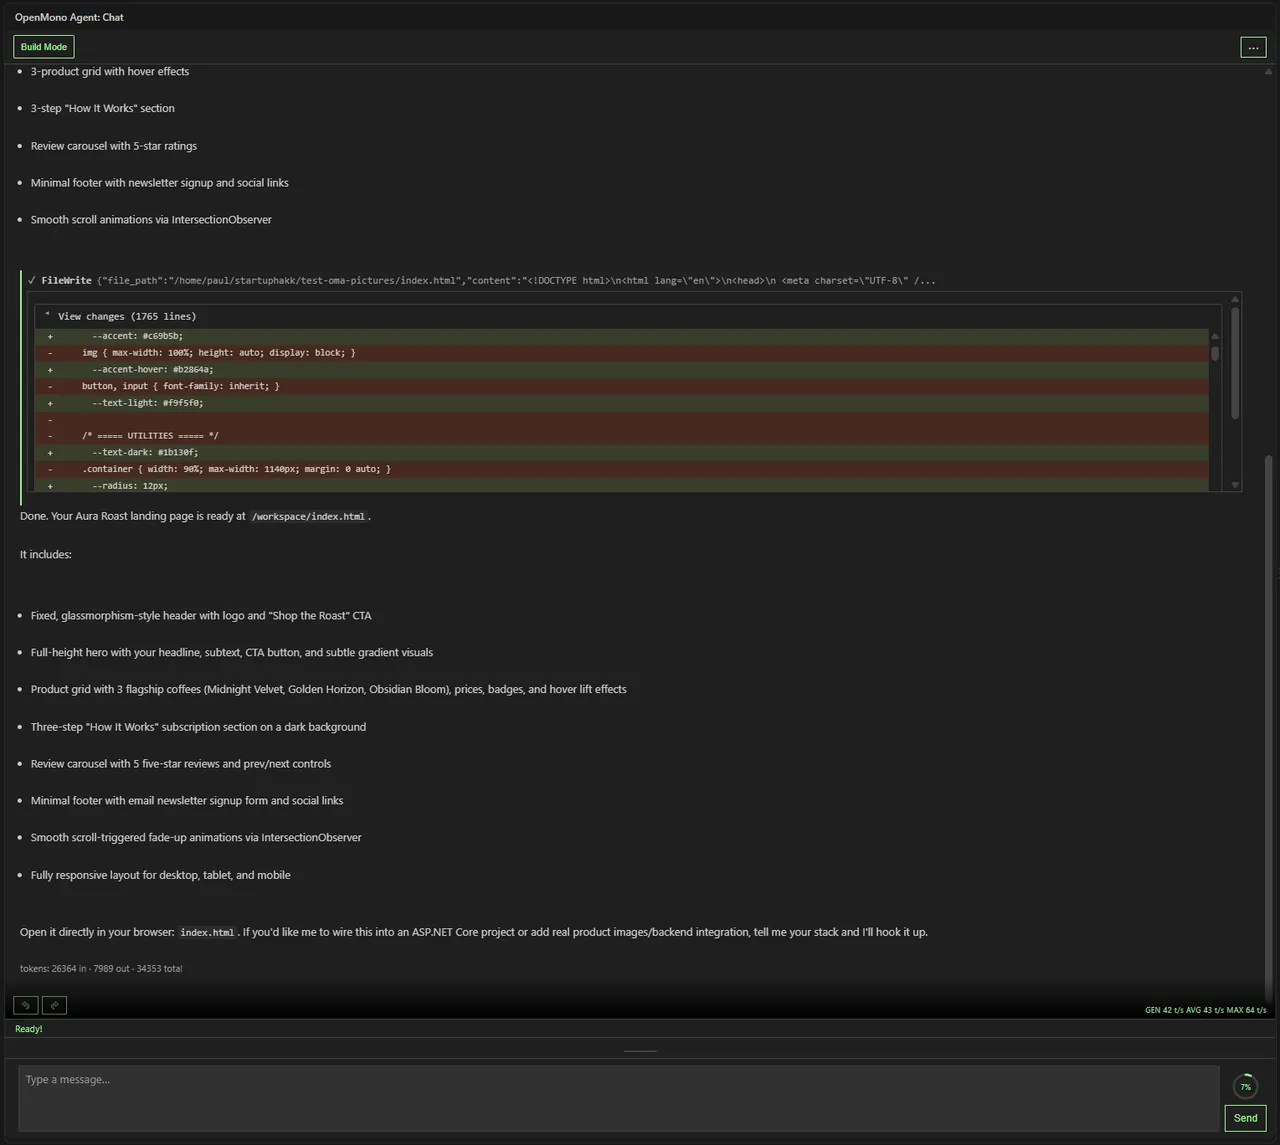
OpenMono now runs inside VS Code and Cursor: local, private, no cloud. Agent chat, Plan/Build modes, permission management, file references with @, and sub-agent support. All the power of OpenMonoAgent.ai, right where you code.

Everything you'd expect from a modern AI coding tool, and a few things you wouldn't, because it doesn't have to phone home. No complex setup required.
Need the agent past the sandbox: services, installs, host logs, docker? Host mode lets it, but every machine-level action goes through a HostExec call you approve first, one at a time. Powerful when you want it, contained when you don't.
Our strongest models yet. Qwen 3.8 27B dense on GPU, Qwen 3.8 Flash-Next streaming from a 48 GB-class box, and Ternary-Bonsai 2 27B where VRAM is tight. Each a big jump over the last generation on agentic coding benchmarks. Auto-picked for your hardware, free to run.
Full agent chat, file references with @, Plan/Build modes, and permission management, directly in your editor. Runs locally, stays private.
Auto-detects your hardware and loads the right model for it. GPU runs Qwen 3.8 27B at full power. CPU drops to Qwen 3.6 35B A3B, lean and still capable. No switching, no config, no API keys. Just run it and it figures itself out. Fully offline.
Full-screen ANSI TUI with streaming tokens, live tok/s meter, context-window usage, auto-compaction, and a flipping hourglass that actually tells you the agent is still thinking.
The agent runs in a container. Your project is bind-mounted in. It can edit your files - but it can't leave the box.
File I/O, shell, search, web fetch, LSP, patches, sub-agents, plan mode. Extend via Model Context Protocol servers.
OpenMonoAgent isn't just built on .NET, it's designed for .NET developers first. Roslyn is baked in, giving the agent real compiler intelligence: type hierarchies, call graphs, cross-assembly references. The agent understands your solution the way the compiler does.
Hover, go-to-definition, and references for C# and TypeScript. Real code intelligence, locally.
Typed, composable, stateful workflow automation. Step sequencing, gates, and templates - not just markdown recipes.
Run the agent on your laptop, inference on your home GPU rig. Outbound-only via relay - works behind any NAT or CGNAT. Signup at app.openmonoagent.ai
JSONL transcripts, cross-session memory, auto-compaction, and snapshot-based file undo. Nothing lost, nothing leaked.
Need help using any of these features?
Tell us what you're building. We'll help you wire it up.
Great coding agents already exist. They're also cloud-locked, metered, and running in someone else's datacenter. We built the third option.
| Claude Code | OpenCode | OpenMonoAgent.ai | |
|---|---|---|---|
| Cost | Per-token | Per-token | Unlimited tokens - Free |
| Privacy | Cloud-only | Cloud + Offline | Fully offline (private) |
| Ease of Install | Simple | Difficult | Simple |
| Local LLM Environment | None | Agent | Agent + Inference |
| Tools | 44 | 15 | 21 + 22 via MCP |
| Written in | npm | npm | C#/.NET |
| Sandboxing | Host install | Host install | Docker-native |
| License | Commercial | Open source | open source |
Still comparing options?
We're happy to walk you through the differences and what works for your setup.
Start from zero. We install OpenMonoAgent.ai on your machine - the model stays local, the agent stays local, your code never leaves your network. Then you use that stack to build and publish a real website and a real browser game to the live web.
Start the free courseNeed help with the course setup?
We'll walk you through the install so you can start building day one.
Clone the repo. Run the installer. Own your AI dev stack before the end of the afternoon.

Direct your self-hosted inference server from anywhere. Full control over your local AI dev stack - no cloud required.
Need help connecting the app to your server?
We'll help you point your phone at your own inference box.